 I’ll clarify the goal and constraints, then organize the information into an actionable path.HOLYCORES
SOLUTIONS
Turn compute into outcomes.
Hardware, software, and engineering support for high-value AI workloads.
WORKLOAD TO PRODUCTION
Not a box. A running AI system.
Start with models, data, and service goals. Combine compute, software, networking, and operations into a production system that can be validated, scaled, and managed.
01 / LLM INFERENCE
Make every generation reach the user sooner.
Plan prefill, decode, KV cache, model parallelism, and serving together for long context, interactive generation, and concurrent demand.
TTFTFirst responseTPOTGeneration paceSCALEConcurrency
02 / ENTERPRISE & SOVEREIGN AI
Bring models inside. Keep data within bounds.
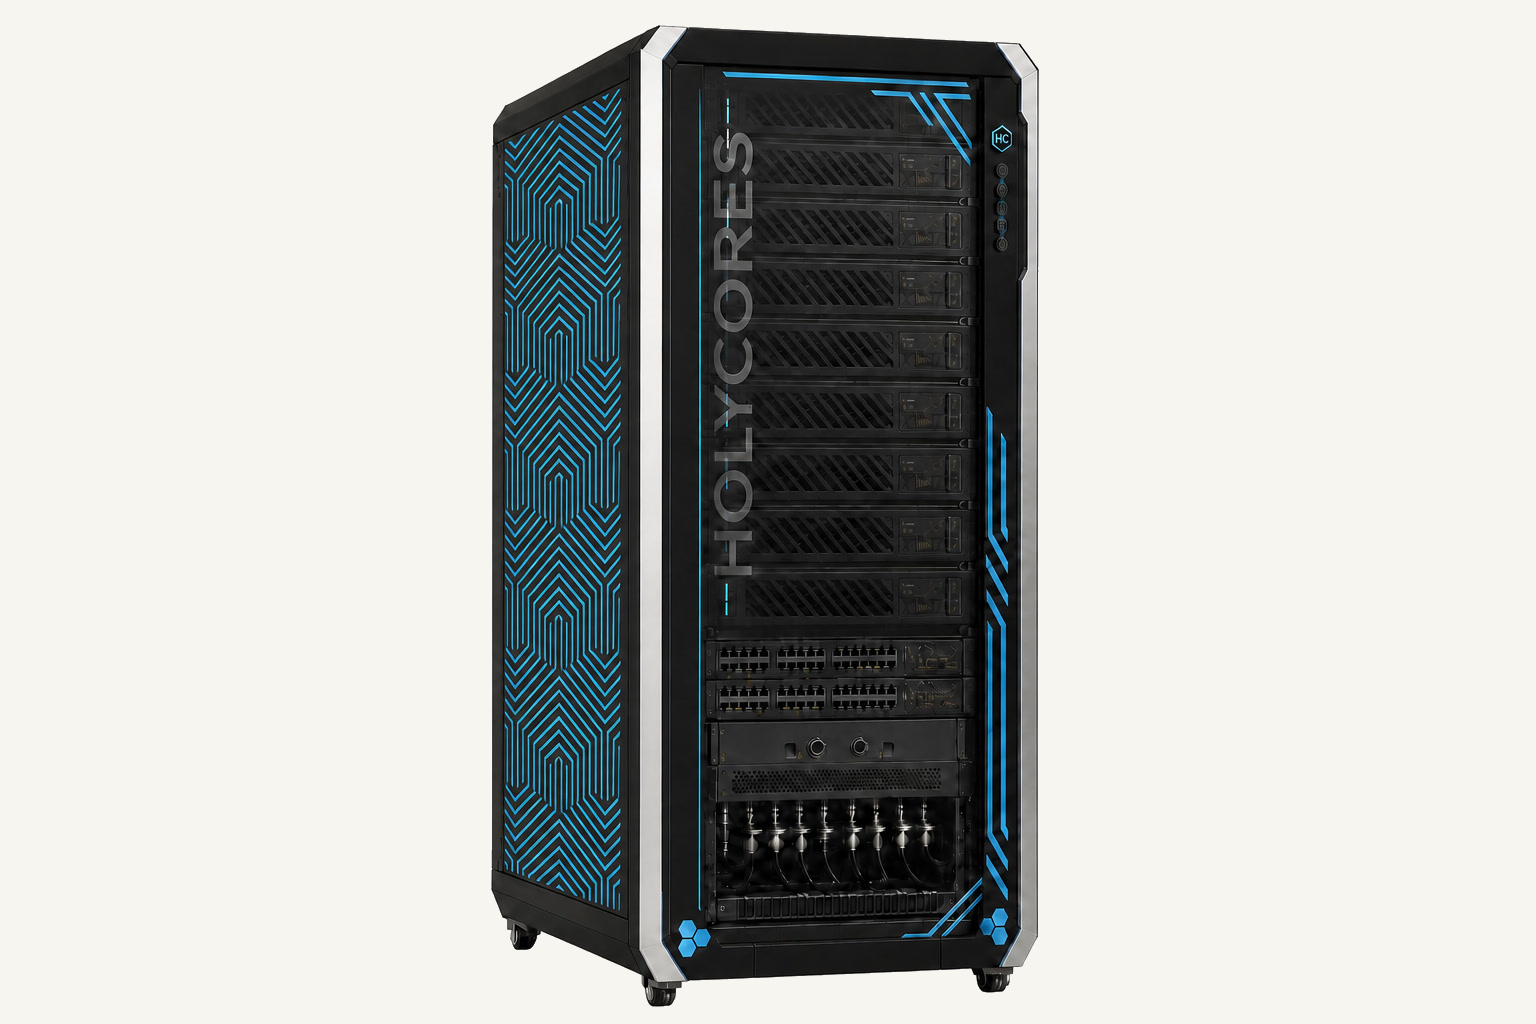
Run enterprise knowledge, internal agents, and domain models on dedicated capacity with auditable operations and a controlled lifecycle.
- Dedicated capacity and data isolation
- Model versions, permissions, and audit
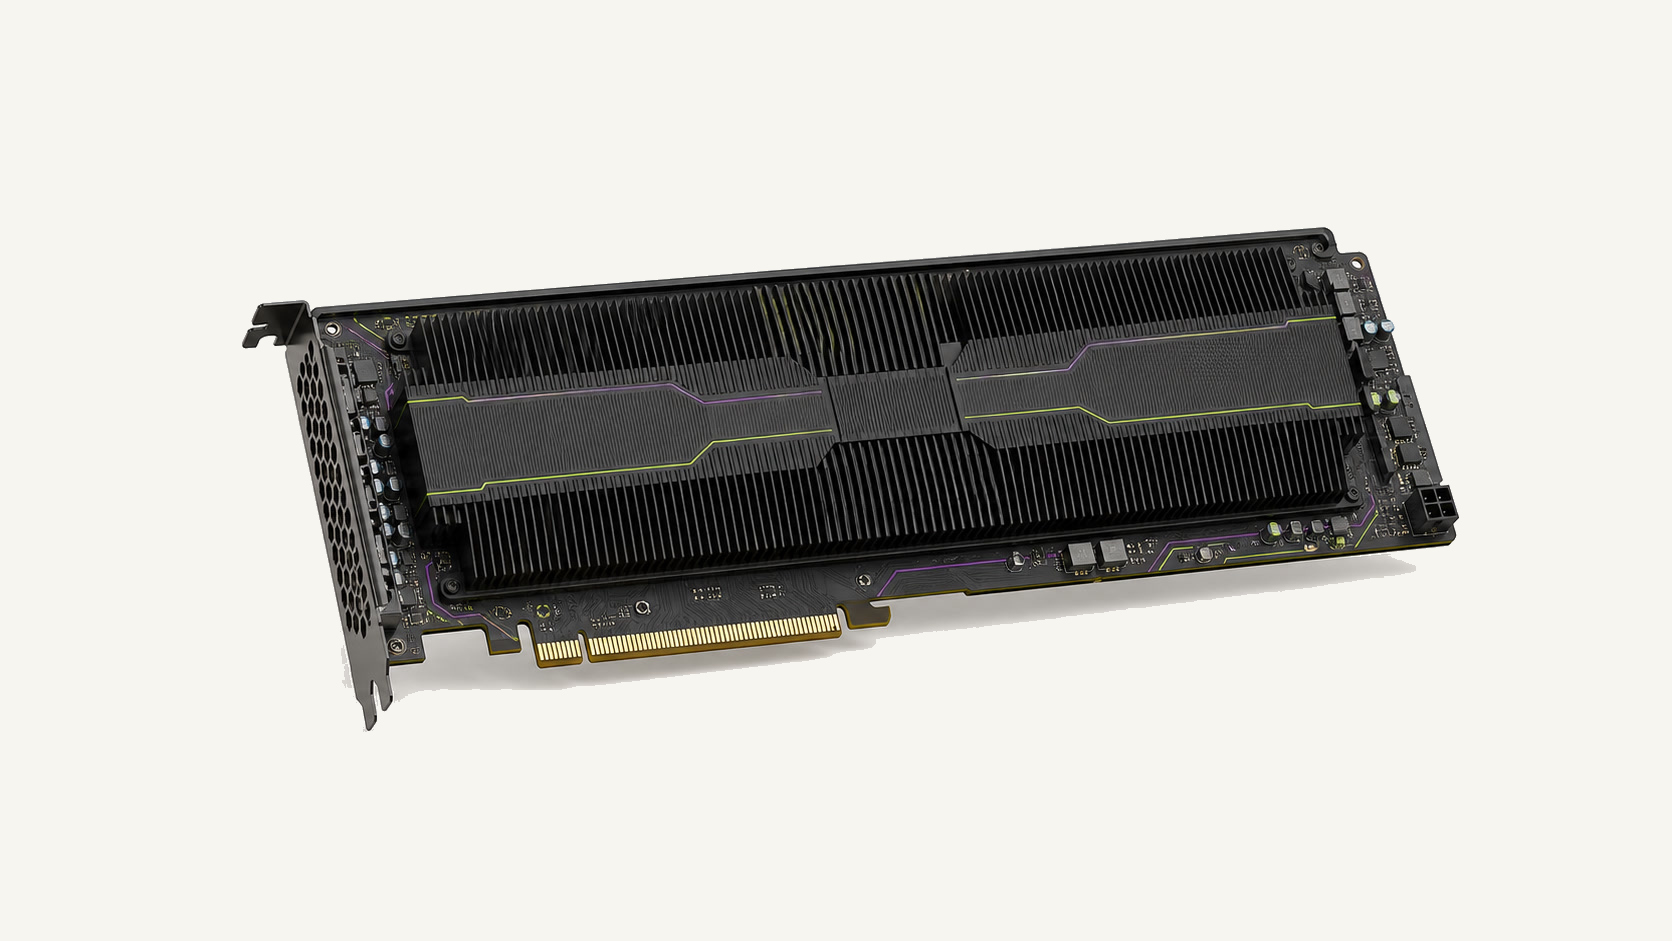
- A path from cards to private clusters
DATAMODELSERVICE
03 / RAG & AGENTIC AI
From one answer to a complete task.
Place retrieval, reranking, reasoning, tool use, and state in one observable pipeline. Optimize end-to-end task time instead of a single model benchmark.
Explore RAG & agents →01RetrieveRETRIEVE
→02RerankRERANK
→03ReasonREASON
→04ActACT
OBSERVE · TRACE · OPTIMIZE04 / PHYSICAL & EDGE AI
Move intelligence closer. Decide without the cloud.
Run perception, fusion, and local decisions for robotics, machine vision, and industrial systems under real power, space, environmental, and timing constraints.
LOCALLocal data loopREAL TIMEDeterministic responseRESILIENTOffline operation
Explore SPARK →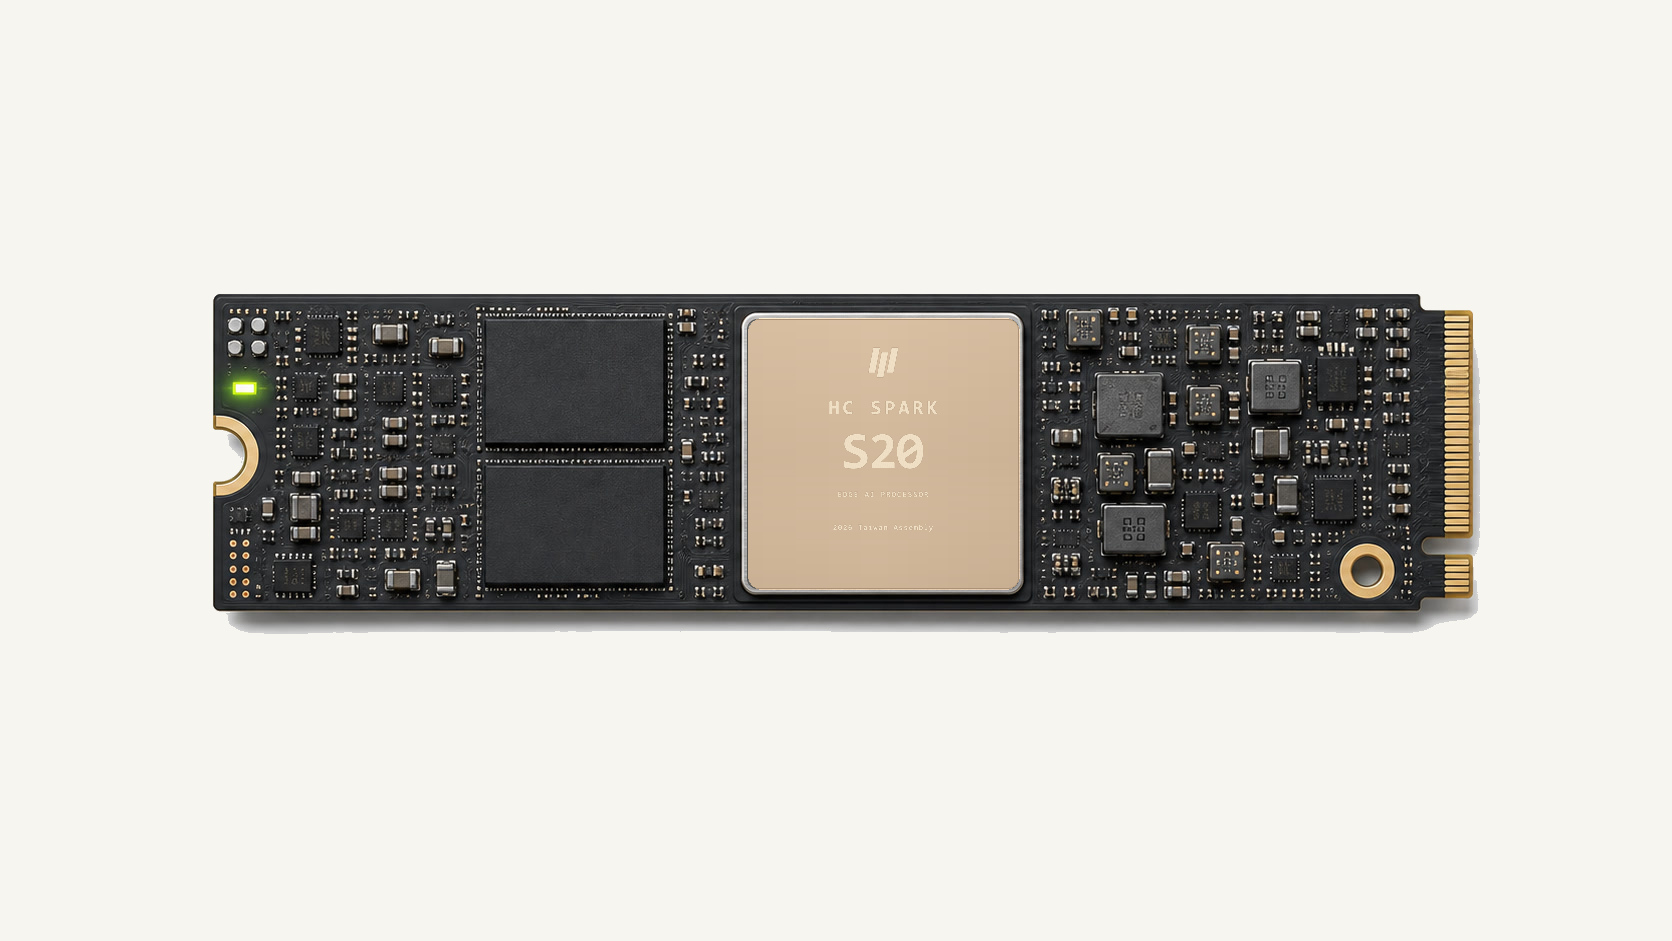
05 / GENERAL AI ASSISTANT
Bring ideas, knowledge, and action into one conversation.
HOLYCORES Chat gives individuals and teams a general AI conversation experience for understanding questions, organizing information, creating content, and moving work forward.
CONVERSENatural interactionCREATEContent and expressionACTTask assistance
HOLYCORES Chat● ONLINEHelp me frame this problem and define the next step.
I’ll clarify the goal and constraints, then organize the information into an actionable path.VALIDATION PATH
From a real workload to continuous operation.
Performance is published only with model, software, precision, context, and concurrency conditions defined.Define
Model, data, baseline, latency, throughput, and deployment boundaries.
Validate
Build repeatable evidence for accuracy, performance, power, and stability.
Integrate
Connect networking, storage, security, serving, and observability.
Operate
Plan capacity, upgrade versions, recover faults, and optimize continuously.
FAQ
Start with the right questions.
How do I choose AETHER, NOVA, or SPARK?+
Define where the workload runs and the system boundary first, then select against model scale, latency, power, data, and operational requirements.
How should LLM inference be evaluated?+
Measure TTFT, TPOT, throughput, concurrency, context, accuracy, and availability together rather than replacing the service outcome with one peak number.
Can validation start small?+
Yes. Establish a card or node baseline with representative models, then scale from evidence into systems and clusters.
READY TO BUILD?