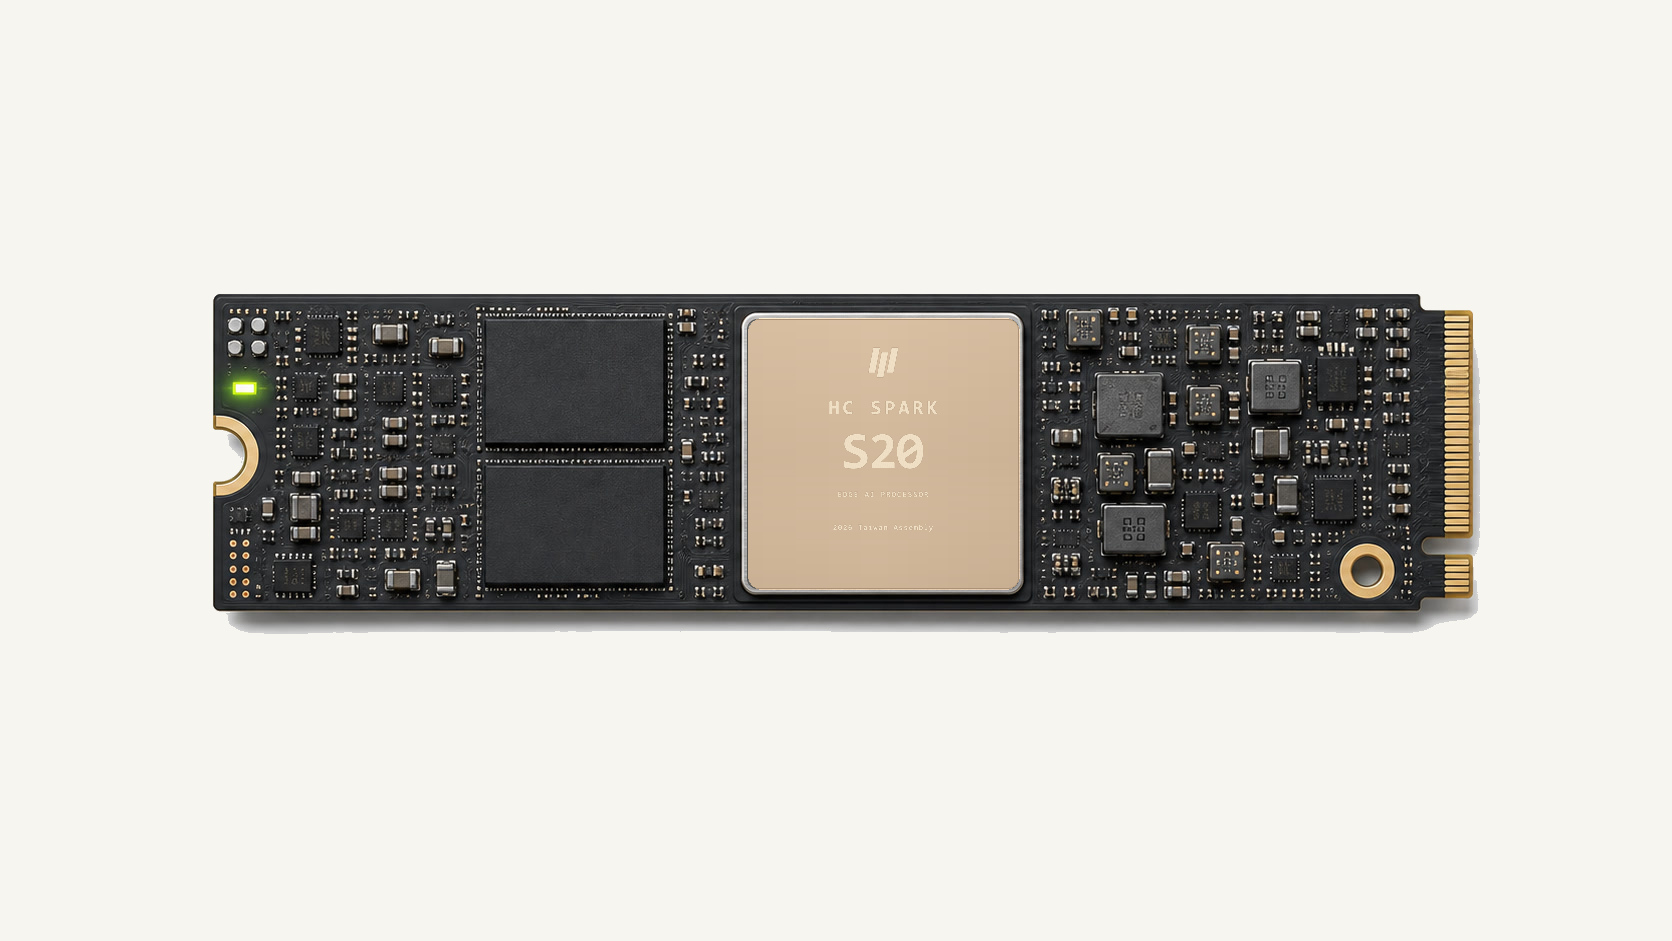
EMBEDDED / 15 W CLASS
SPARK S20
A compact M.2 module for low-power local inference in robots, cameras and intelligent terminals.
 HOLYCORES
EDGE AI PROCESSOR
Real-time AI in low-power edge devices.
SPARK MODULES
A compact M.2 module for low-power local inference in robots, cameras and intelligent terminals.
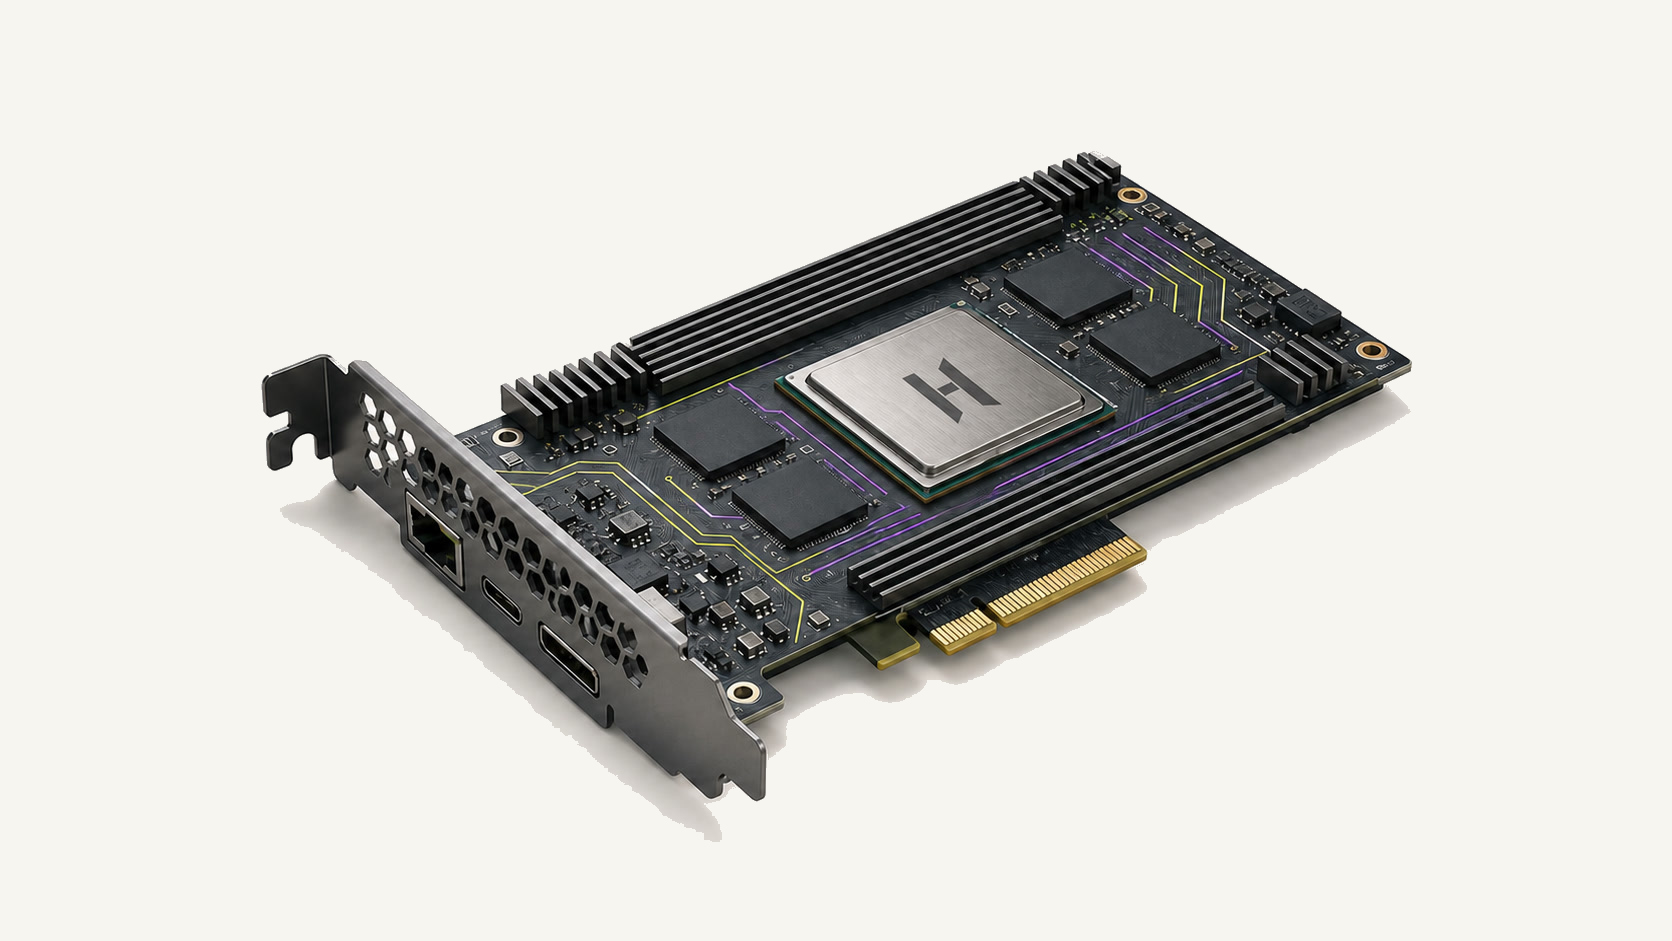
A low-profile PCIe module for embedded servers, industrial vision and multi-model pipelines.
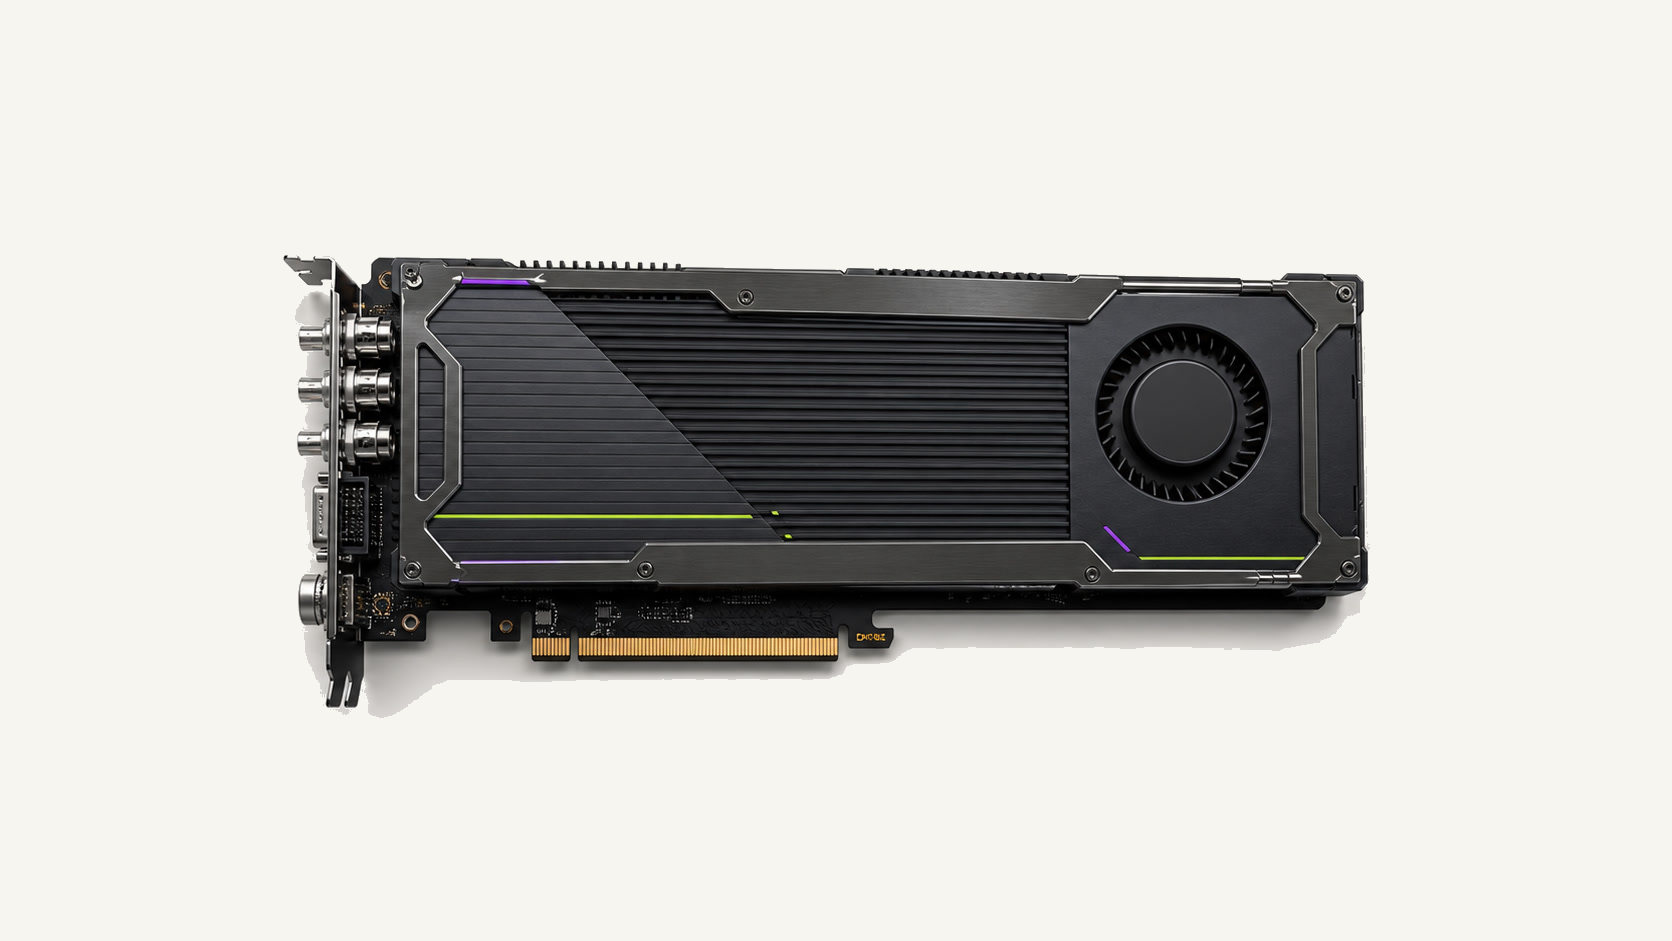
An actively cooled, industrial-I/O edge card designed for sustained multi-camera and robotics-server workloads.
COMPARE SPARK MODELS
| Planning dimension | SPARK S20 | SPARK S40 | SPARK S80 |
|---|---|---|---|
| Format | M.2 module | Low-profile PCIe card | Rugged PCIe card |
| Relative compute | 1× baseline | Approx. 2× S20 | Approx. 4× S20 |
| Target memory | 8 GB | 16 GB | 32 GB |
| Host interface | PCIe 4.0 ×4 | PCIe 4.0 ×8 | PCIe 5.0 ×8 |
| Target power | Up to 15 W | Up to 35 W | Up to 75 W |
| Cooling | Passive | Passive / active options | Active |
| Target deployment | Cameras, robots, terminals | Embedded hosts, vision | Multi-camera, edge servers |
Planning targets may change after silicon, board, interface, environment and reliability validation.
DESIGN PERSPECTIVE
Reuse model and operator work across deployment targets.
Co-design compute, fabric, cooling, and operations around real workloads.
Start with validation, then expand to clusters and edge fleets.
Every engagement connects architecture, software, validation, and production operations.
ENGAGEMENT MODEL
FAQ
These pages describe product direction. Availability, specifications, and schedules will be confirmed in formal product materials.
It reduces repeated engineering when models move between deployment environments.
The planned path starts with development and validation before scaling to production.
CHOOSE YOUR PERSPECTIVE
Understand platform scope, deployment choices, and the long-term path.
Follow this path →Evaluate compute, fabric, software, operations, and facility constraints.
Follow this path →Focus on model entry points, operators, tooling, and portability.
Follow this path →TECHNICAL EVALUATION
| Dimension | Question | Validation |
|---|---|---|
| Compute architecture | Adapt to different models and precision strategies | Build utilization and accuracy baselines with representative workloads |
| Memory hierarchy | Reduce avoidable movement and bandwidth stalls | Profile working sets and end-to-end bottlenecks |
| Scale-out fabric | Grow from device to node and cluster | Validate topology, communication, and scaling efficiency |
| Software stack | Map framework models reliably to hardware | Check coverage, correctness, and tunability |
| System engineering | Balance power, cooling, density, and serviceability | Validate against the target facility and workload |
| Operations | Deploy, observe, upgrade, and diagnose | Establish telemetry, health, version, and rollback workflows |
WORKLOAD MAP
Throughput, communication, precision, and long-run stability.
Response time, generation rate, concurrency, and utilization.
Data boundaries, operational control, auditability, and lifecycle.
Local latency, power, interfaces, and environment.
ADOPTION PATH
Create a baseline with representative models and evaluation systems.
Integrate with customer security, datacenter, and operational practices.
Expand clusters or edge fleets against capacity and service goals.
PRODUCTION READINESS
Health, fault isolation, recovery, and long-run validation.
Boot, identity, access, update, and data-boundary planning.
Telemetry that connects model behavior to system state.
Versioning, compatibility, rollback, maintenance, and support.
RESOURCES & STATUS
Product direction, architecture principles, workloads, and evaluation framework on this site.
Workload definition, environment requirements, success metrics, and test planning.
Specifications, compatibility, SDKs, docs, release notes, and validated model status will follow maturity.
Local inference for robotics, vision, and industrial equipment.
Move models from NOVA validation to SPARK deployment.
READY TO BUILD?