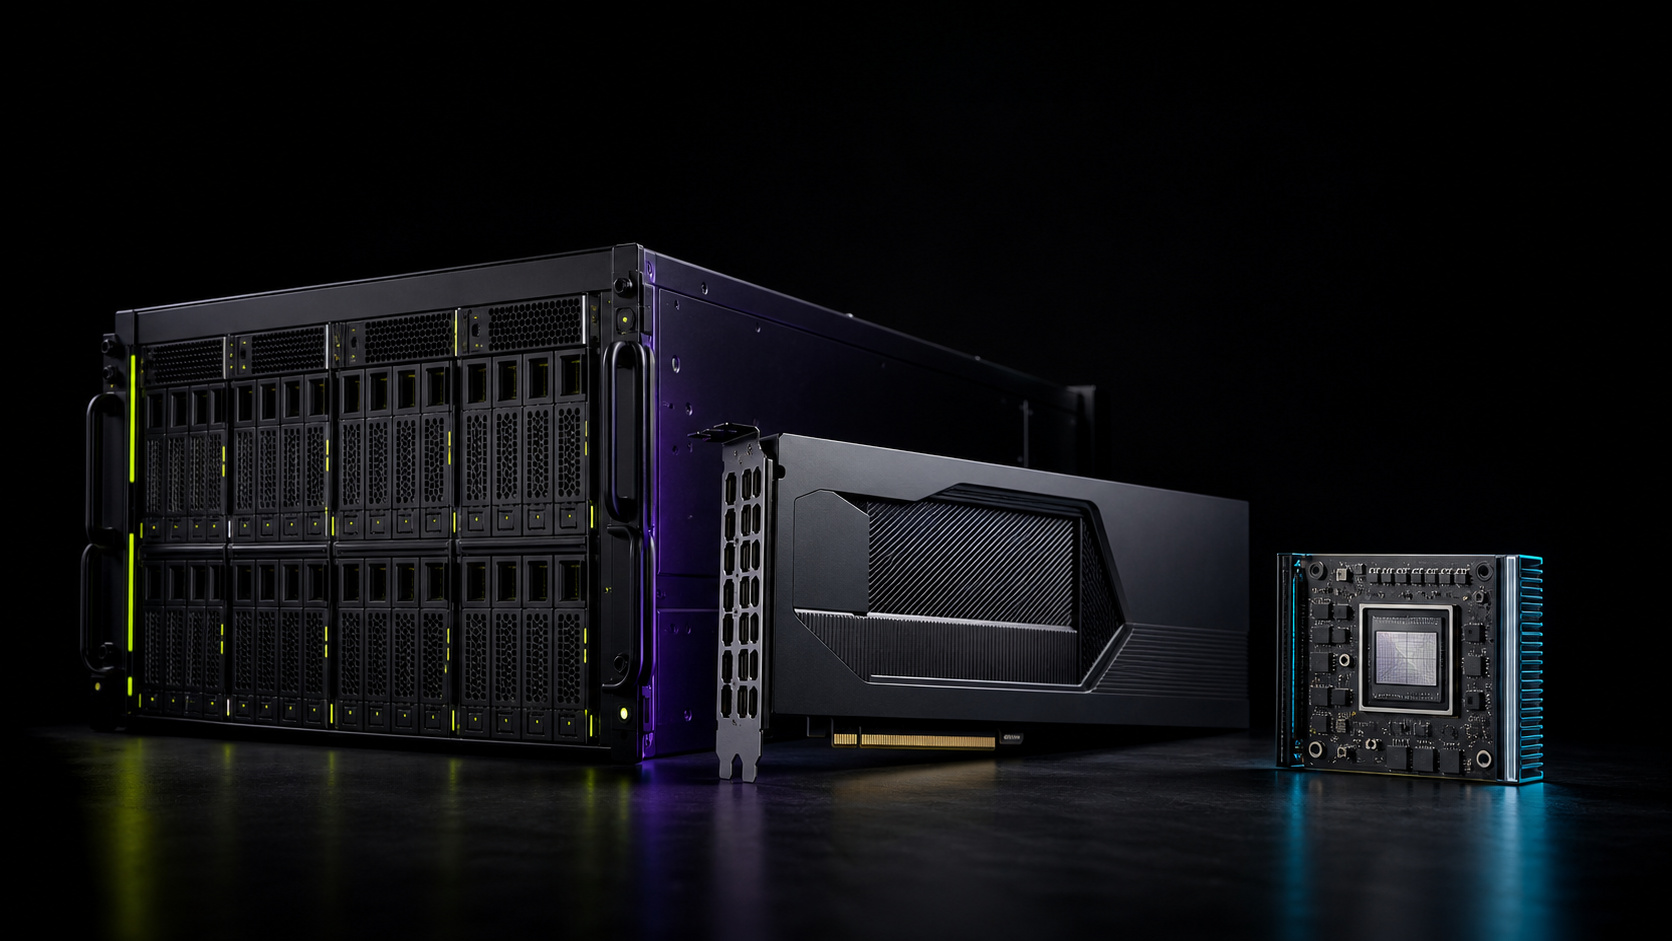
Broader access to AI
Extend intelligence from centralized infrastructure to private environments and field devices, with the right form factor for every scale.
 HOLYCORES
COMPUTE AT EVERY SCALE
AETHER, NOVA, and SPARK share one open compute foundation.
WHY HOLYCORES
Extend intelligence from centralized infrastructure to private environments and field devices, with the right form factor for every scale.
Reduce unnecessary data movement and run latency-sensitive models where results are needed.
Support local and private deployment for sensitive information, regulated industries, and critical operations.
Evaluate utilization, capacity, energy, and operations around real workloads—not isolated peak numbers.
Use dataflow, hardware-software co-design, and layered deployment to reduce waste across the system.
HARDWARE PORTFOLIO
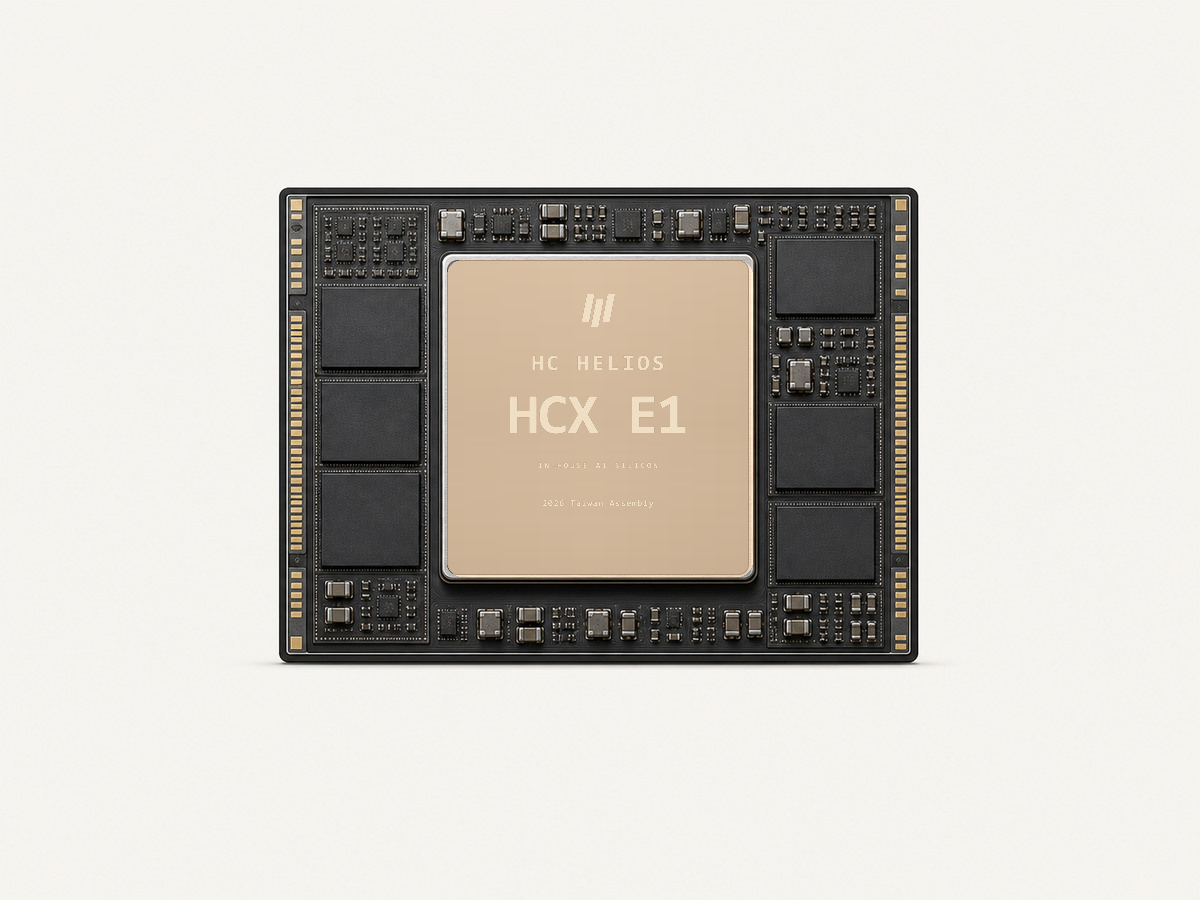
Designed in-house, from the silicon up. A shared compute, memory, fabric and software foundation for datacenter, edge and advanced packaging.
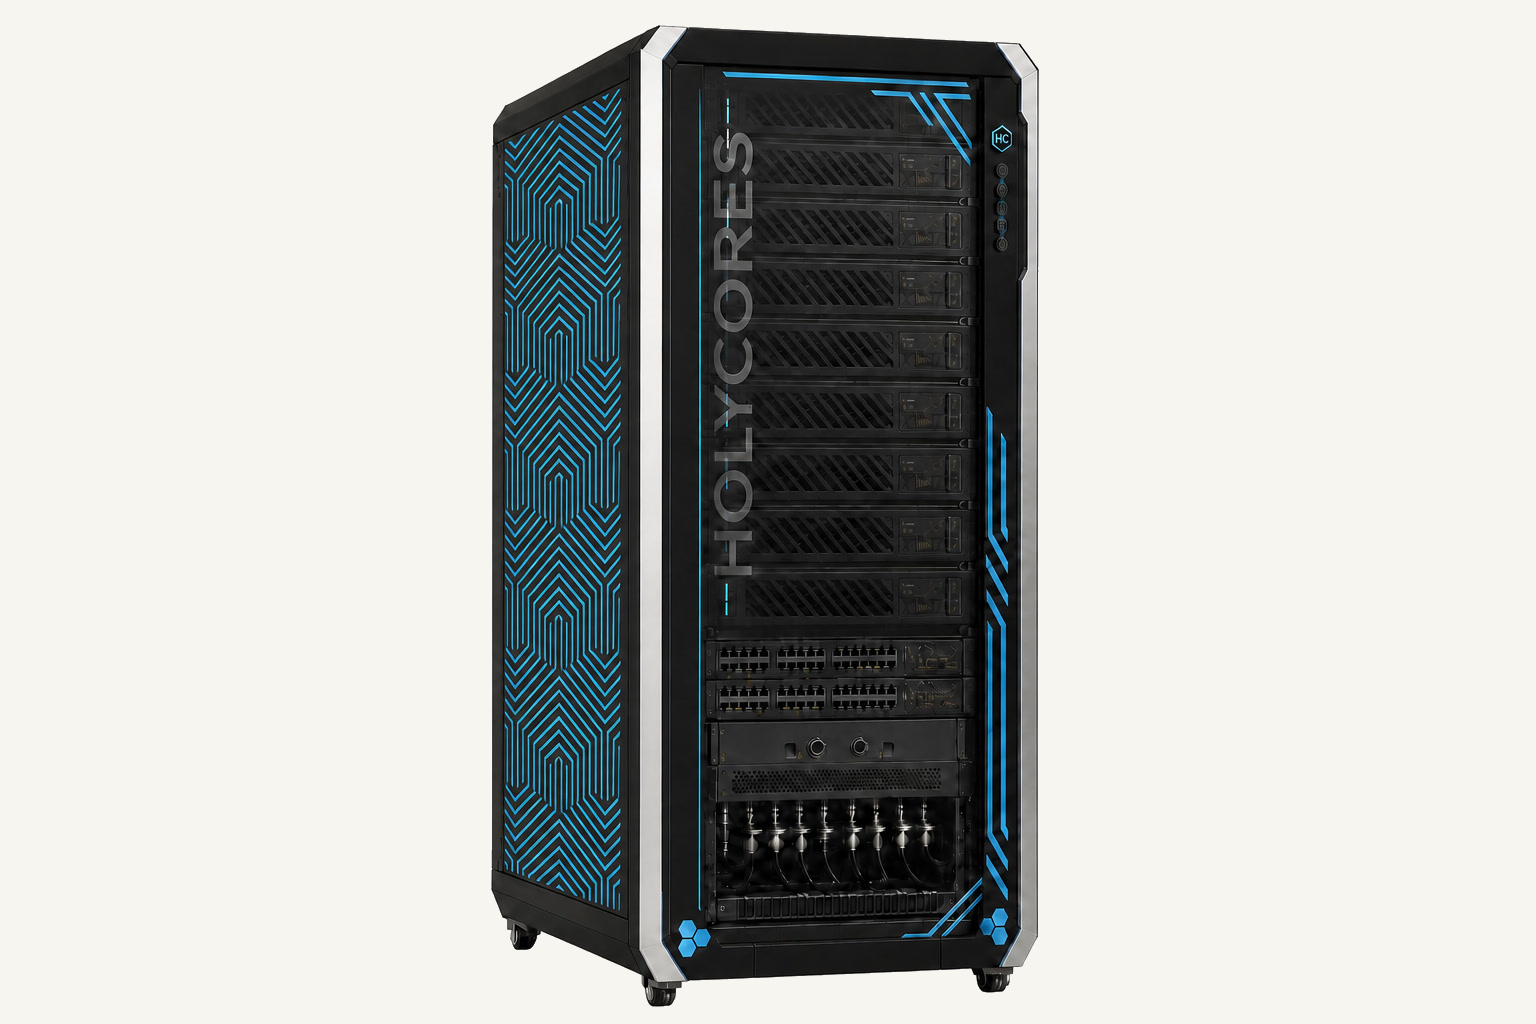
An integrated rack bringing compute, fabric, liquid cooling, telemetry and management into one production system.
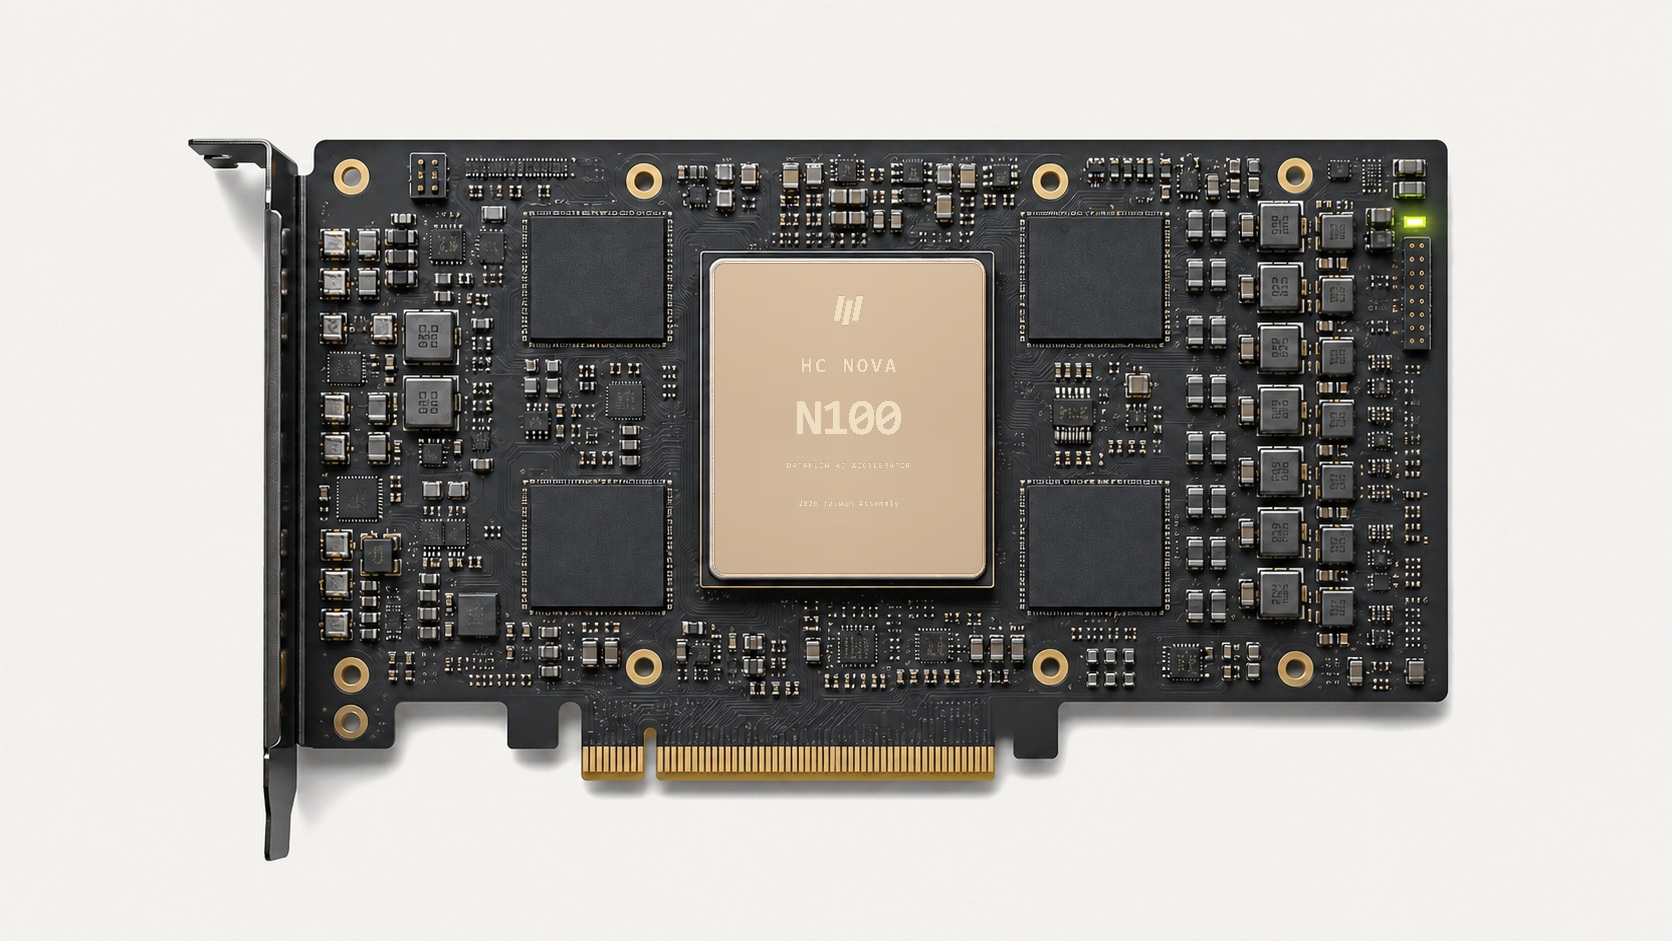
A single-chip PCIe accelerator for developer workstations, private AI, and general inference servers.
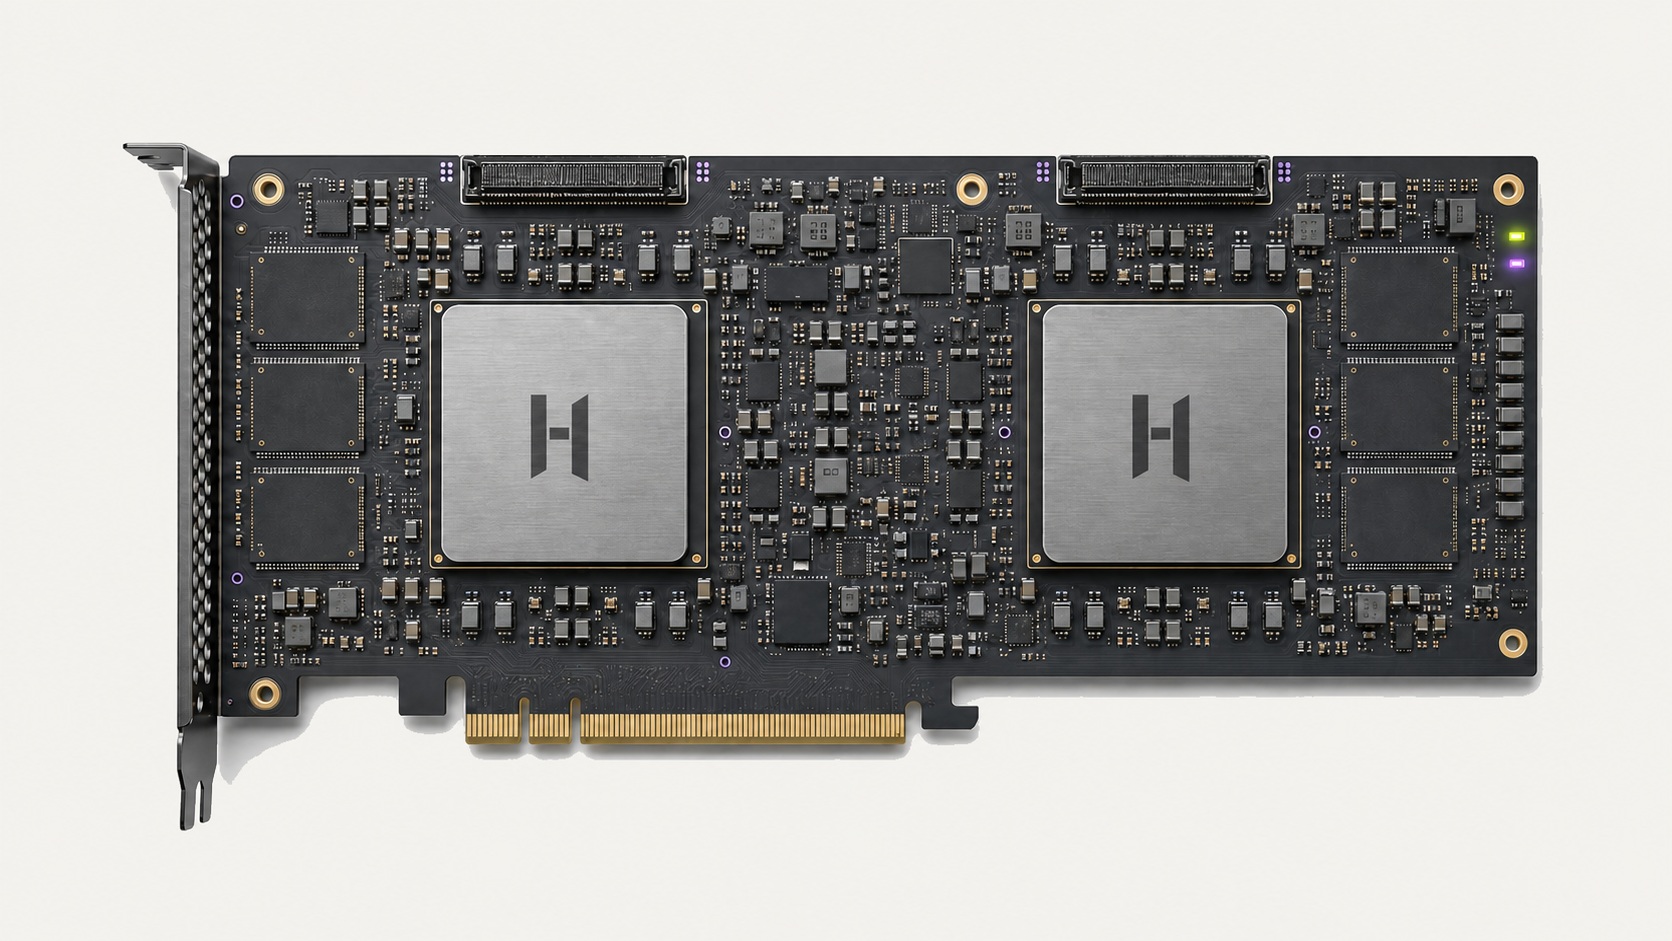
A dual-chip platform with dedicated card fabric for throughput, multi-card scaling, and dense servers.
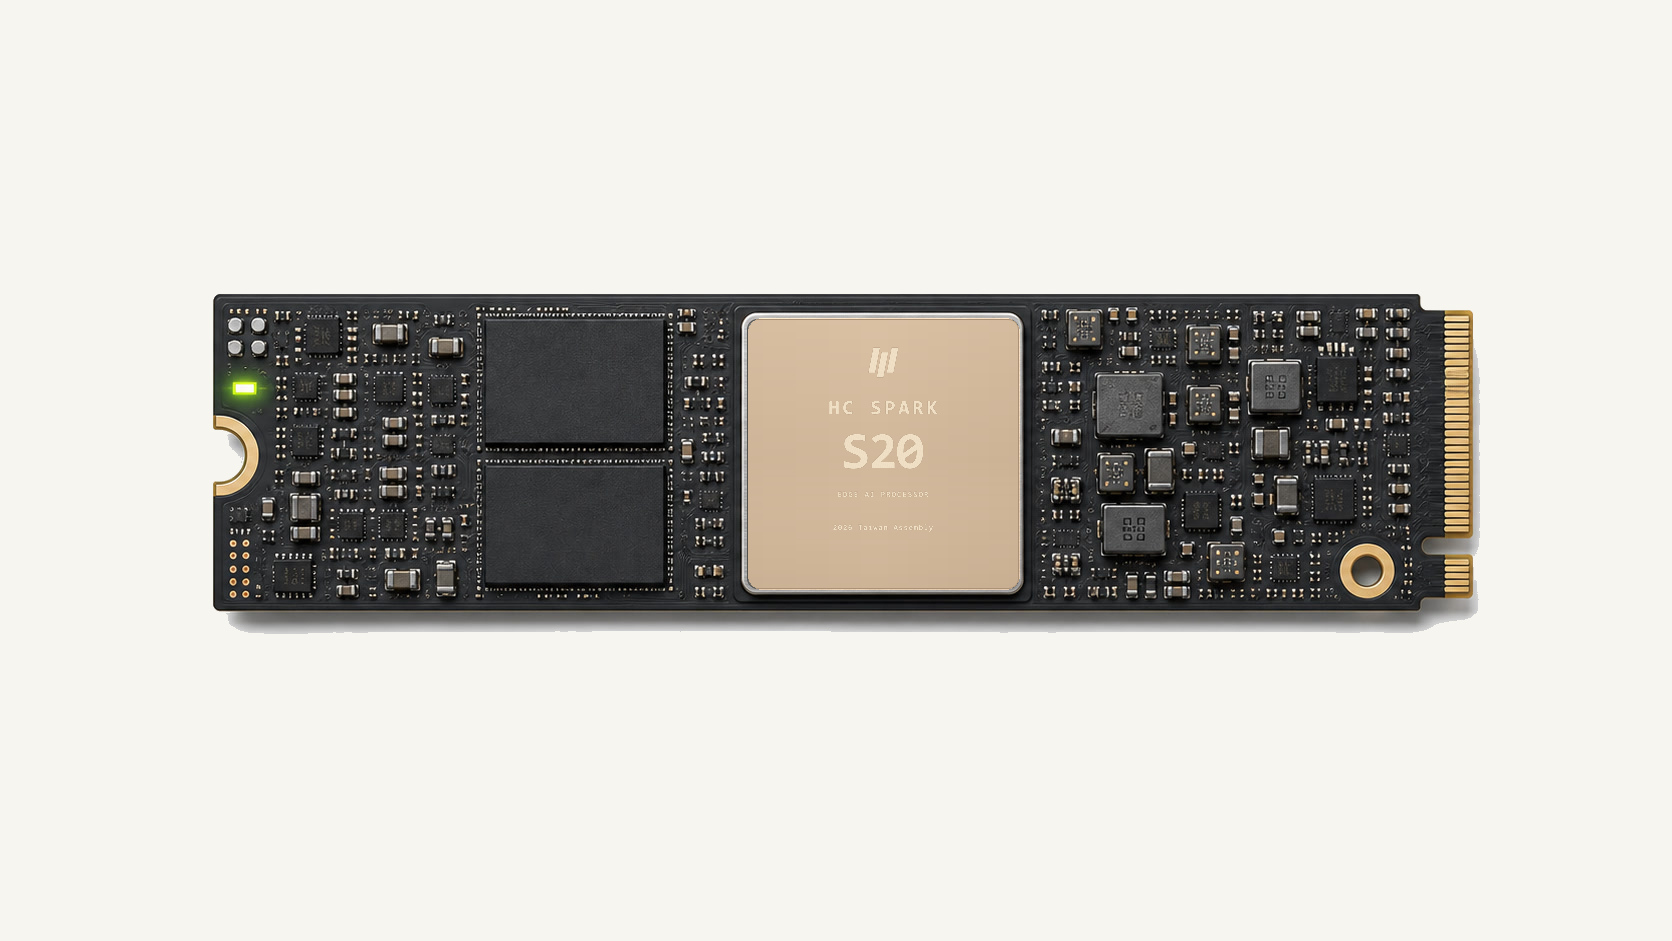
A compact, low-power local inference module for robotics, vision, and intelligent devices.
COMPARE NOVA MODELS
| Planning dimension | NOVA N100A | NOVA N200A | NOVA N200P |
|---|---|---|---|
| Form factor | Single-chip active card | Dual-chip active card | Dual-chip passive card |
| Relative compute scale | 1× baseline | Approx. 2× N100A | Approx. 2× N100A |
| Target memory | 24 GB | 48 GB | 48 GB |
| Host interface | PCIe 5.0 ×16 | PCIe 5.0 ×16 | PCIe 5.0 ×16 |
| Card fabric | Host PCIe | 2× HC-Fabric | 2× HC-Fabric |
| Target board power | Up to 225 W | Up to 350 W | Up to 300 W |
| Cooling | Dual-slot active | 2.5-slot active | Dual-slot passive |
| Target deployment | Developer workstations, inference servers | High-throughput inference, multi-card nodes | High-density rack servers |
Planning targets may change following silicon, board, thermal, and system validation. Final availability, compatibility, and specifications will be defined in future product materials.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
DEEPER VIEW
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Explore →Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Explore →Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Explore →DECISION FRAME
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
NEXT STEPS
Create a clear output and decision gate for this stage.
Create a clear output and decision gate for this stage.
Create a clear output and decision gate for this stage.
PRODUCT EVALUATION
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
Choose by deployment location, model scale, latency, power, and operations—not a single peak metric.
FAQ
Share a non-confidential workload, environment, current baseline, and decision goal.
Availability, compatibility, and validated specifications will be published by product maturity.
Production infrastructure combining dense compute, high-bandwidth fabric, and unified operations.
A programmable platform for training, fine-tuning, and inference.
Low-power processors for robotics, vision, and real-time AI.
READY TO BUILD?